Microsoft bug undetected since July triggered worldwide outage
Company spent 15 hours identifying, deploying the fix

The bug that crippled Microsoft Corp. productivity software last week had been lurking undetected in the company’s data centers since July.
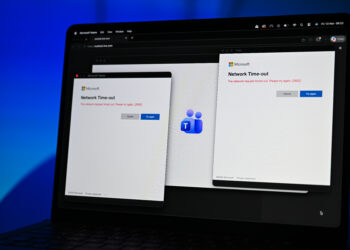
When the software maker did some routine rerouting of user traffic on Nov. 11, the system malfunctioned. Then servers critical to Outlook, Teams, the Copilot AI assistant and several other services, began to fail — ultimately triggering outages for people around the world.
Microsoft had little inkling it had a problem brewing for about 15 hours, according to a preliminary report the company issued to customers on Sunday. Microsoft then spent another 15 hours identifying and starting to roll out the fix — an eternity for a wired world that relies heavily on the company’s software.
Just after 8 p.m. New York time on Nov. 11, traffic from the Teams videoconference and chat service was automatically rerouted to the separate system of servers that also handle Outlook traffic. That, combined with a loss of server capacity caused by an unrelated issue earlier in the week, triggered the bug, which prompted servers to exhaust their memory after an unexpected surge in traffic.
Servers began to fail. The problem was worsened by automated systems that rerouted emails and user traffic to what Microsoft’s system thought were other, healthy servers, causing the bug to show up there, too. By 11:30 a.m. on Nov. 12 – just as traffic from business in the US was reaching its peak – Microsoft realized it had a problem.
It took the company another 15 hours of troubleshooting to start deploying a fix for the issue. In the meantime, work at many of Microsoft’s corporate and government clients ground to a halt, as email inboxes failed to load, Teams invitations went missing and workers resorted to phone calls and pen and paper.
The outage was an embarrassment for Microsoft, and a reminder of the risks of relying so heavily on a single technology vendor. Charles Lamanna, the Microsoft executive vice president who oversees the company’s workplace software, apologized early Monday for the outage in a post on the X social media site that offered more detail on what went wrong.
A more comprehensive timeline, included in an update for technologists who use the Microsoft 365 bundle of software, showed how the company’s automated efforts to keep its software running helped spark a cascading failure. At the nadir on Thursday, more than 80% of the servers behind Outlook were unresponsive.
Such outages often last just a few hours at most. In this case, it took longer because as soon as servers returned to service, they were overwhelmed by waiting traffic and failed again. And because the bug had gone unnoticed for months, efforts to stabilize the system by rolling back recent updates had no effect.
Microsoft tests changes to its network in labs and on small portions of its network before deploying them widely, standard protocol for companies that support large online services.
This bug wasn’t caught, Lamanna said, because the simulated traffic patterns and hardware in the company’s labs didn’t reflect the real-world conditions the servers later encountered. Microsoft’s testing typically focuses on older and weaker systems to assess whether updates will trip up the weakest link in the company’s cloud. The bug that caused servers to seize up is more destructive on newer hardware with more processing power.
— By Matt Day (Bloomberg)